Overview
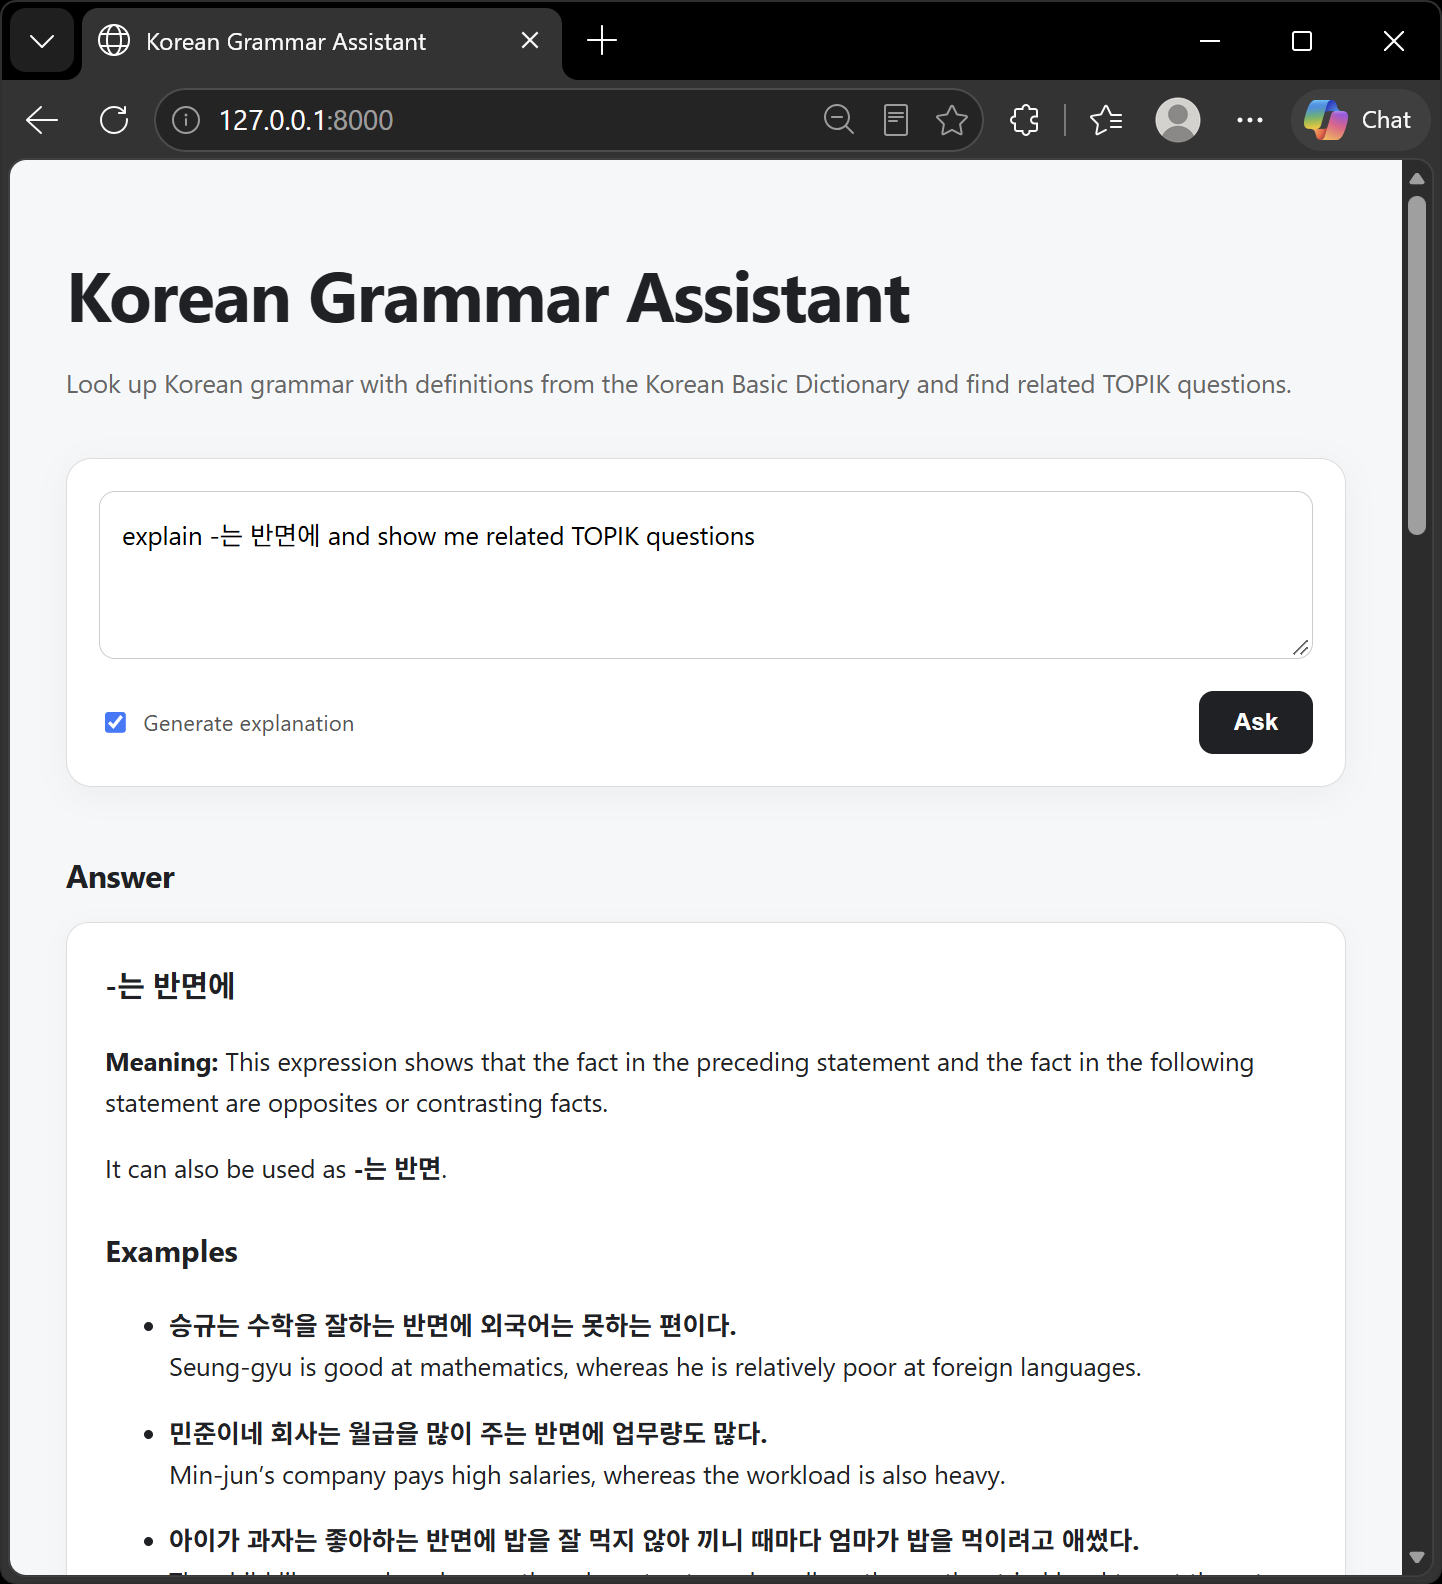
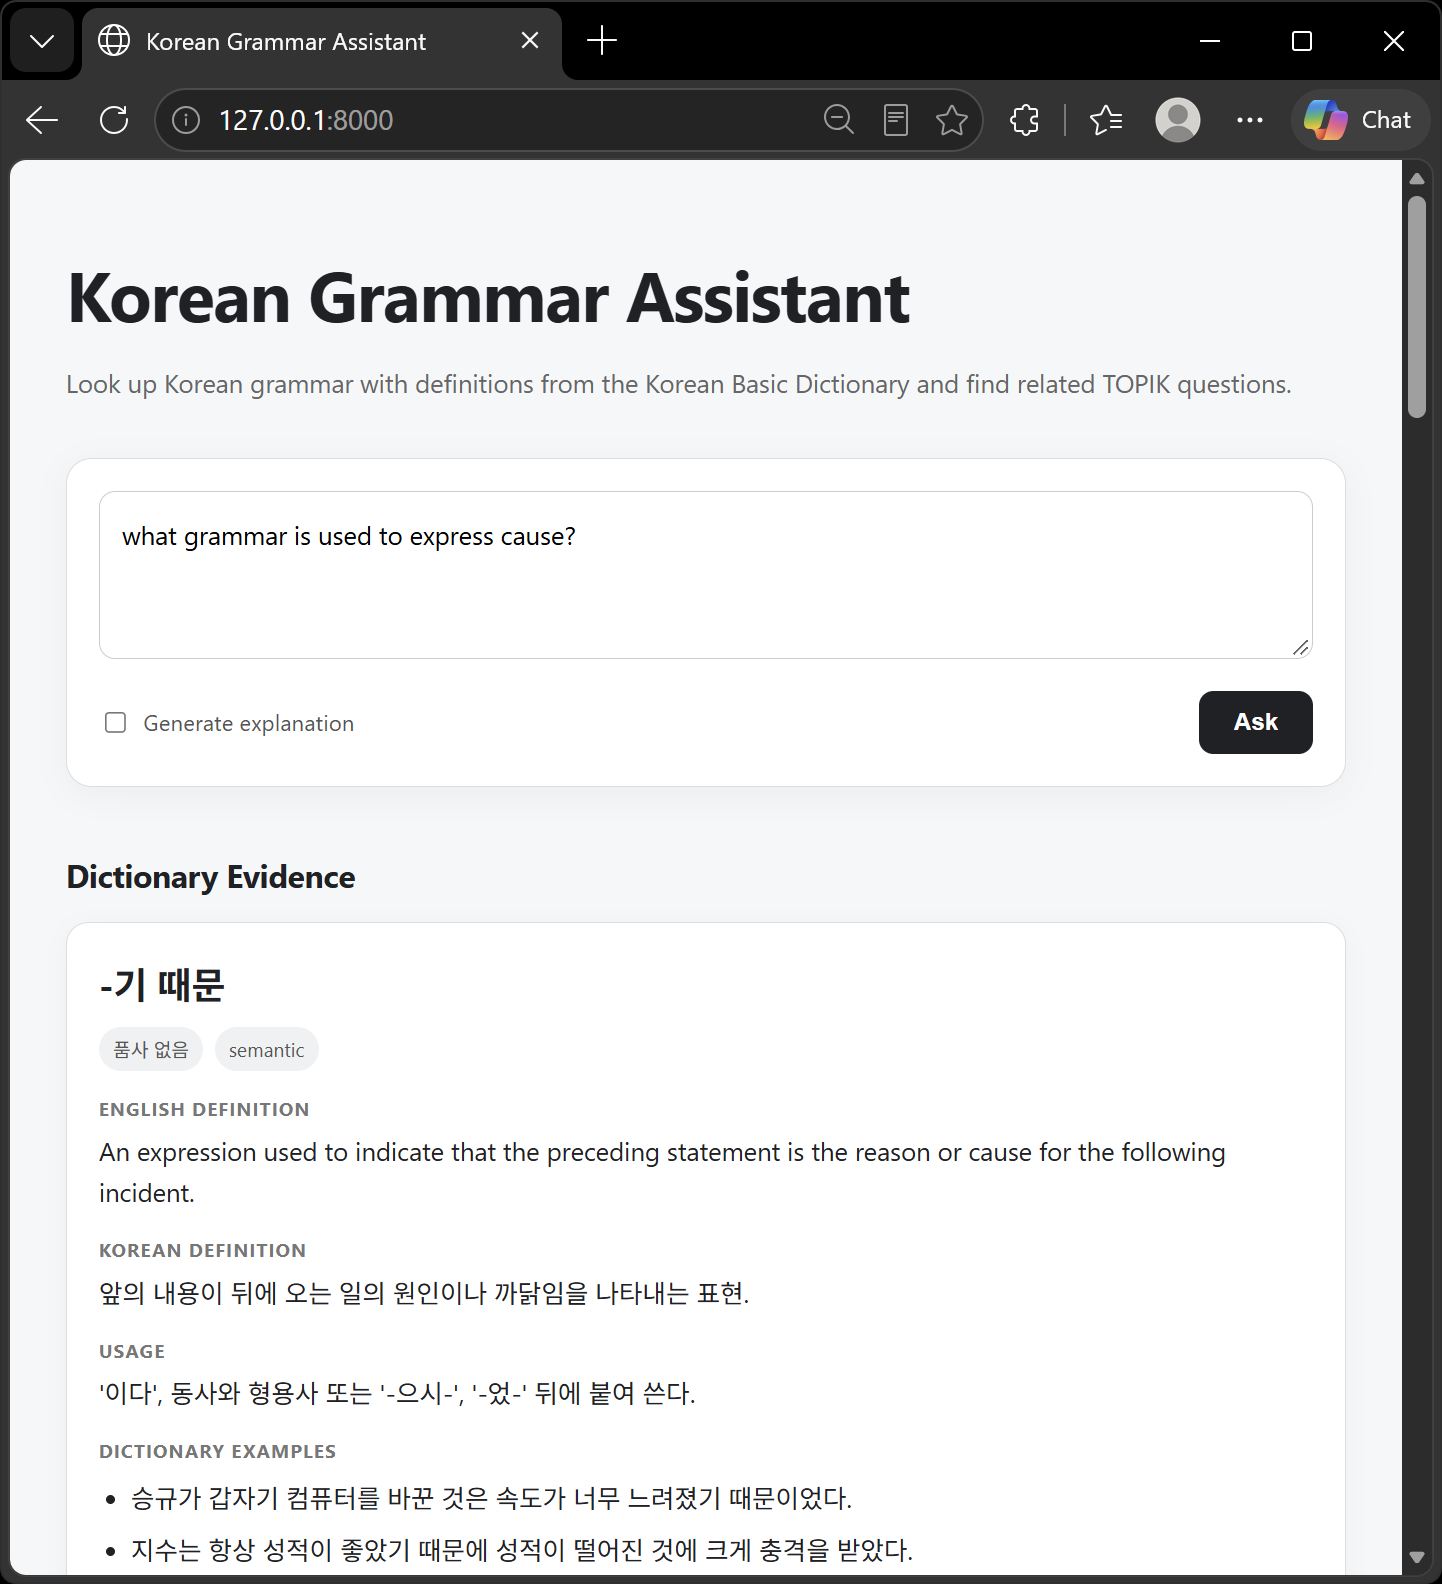
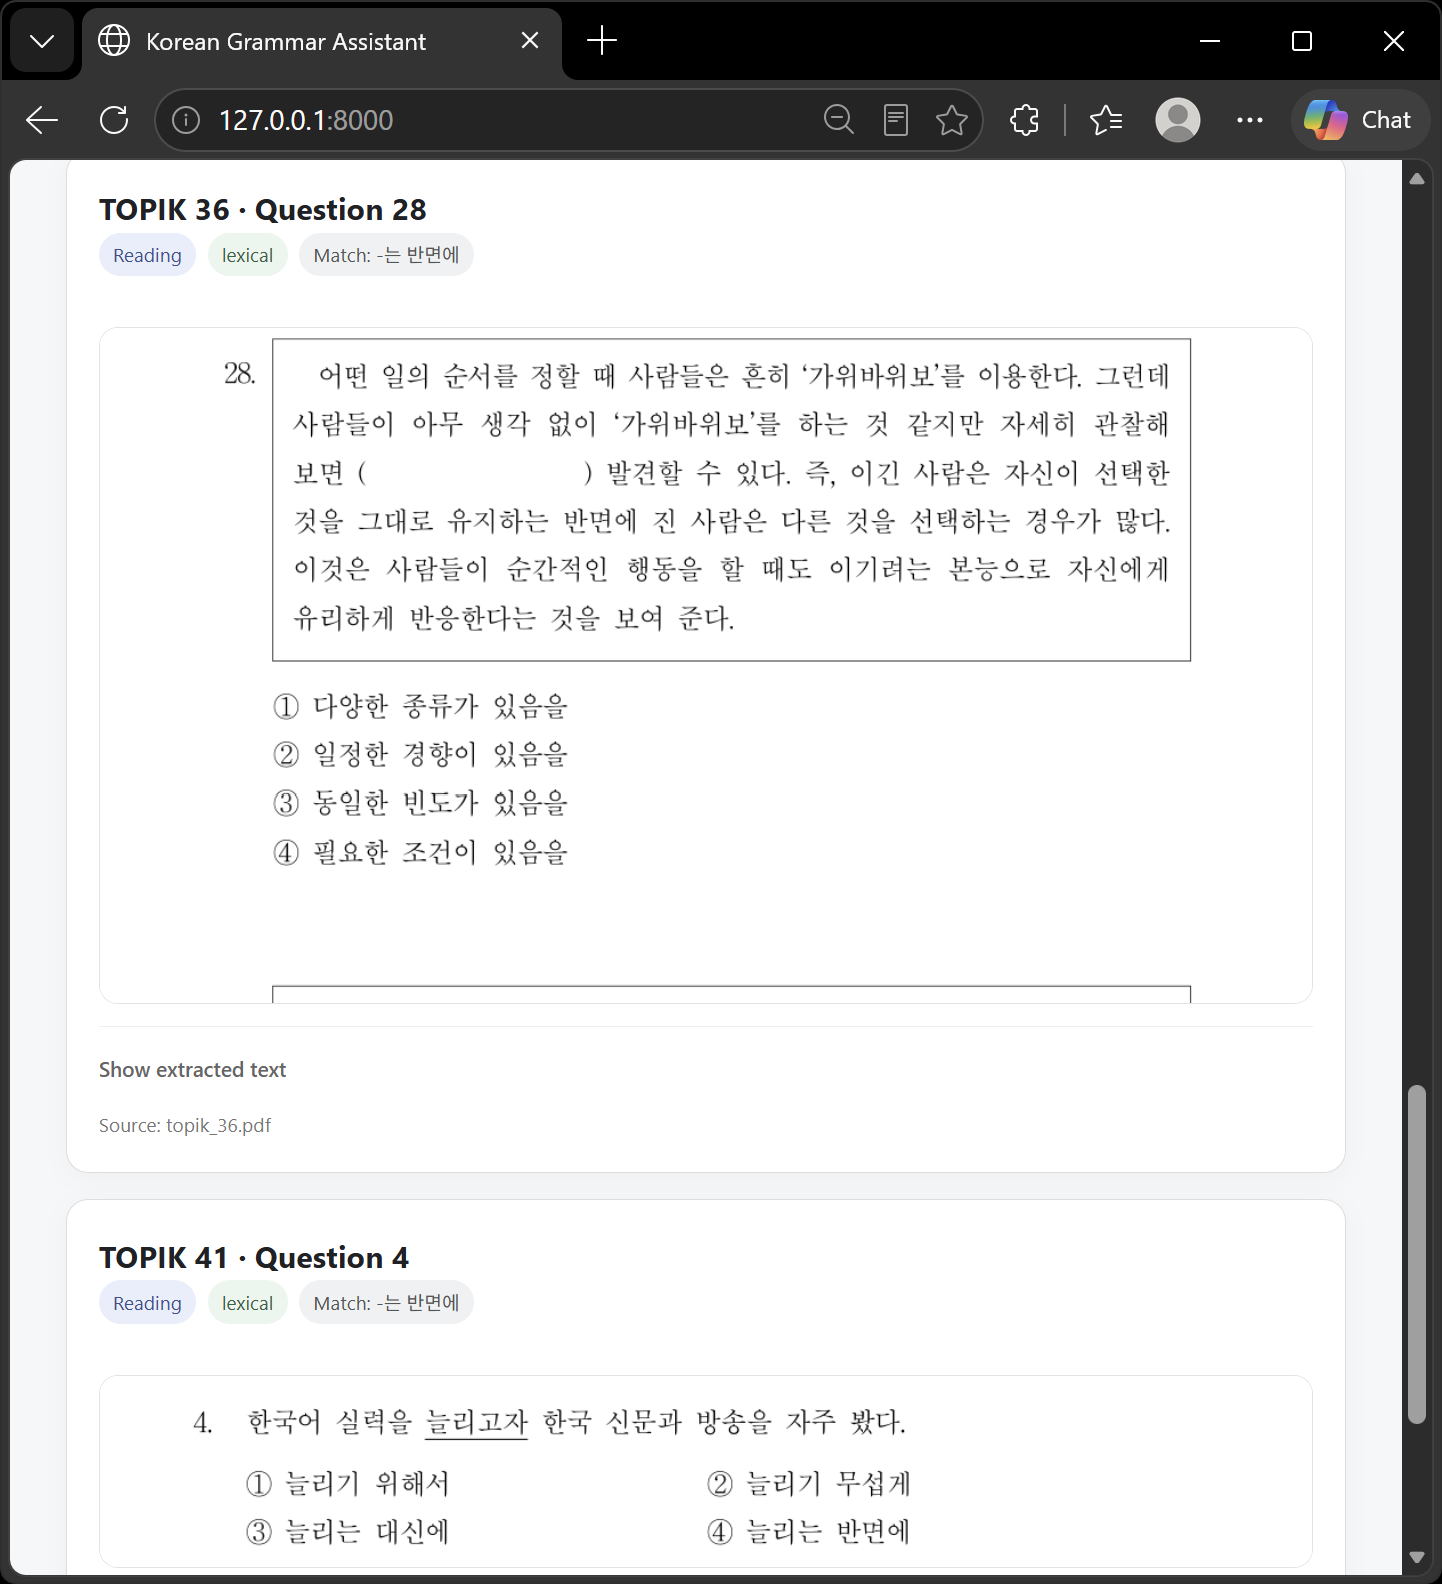
I built this project to make Korean grammar lookup faster and more useful for studying. Grammar explanations are based on entries from the Korean Basic Dictionary rather than generated from the language model's knowledge alone. The system can also search past TOPIK reading exams and show real questions where the same grammar form or a related topic appears.
Objectives
- Answer direct grammar questions as well as broader searches, such as finding grammar used to express contrast, cause, uncertainty, intention, etc.
- Support both Korean and English queries using multilingual semantic search.
- Use the Korean Basic Dictionary as the source for grammar explanations and TOPIK papers as real exam examples.
- Process both text-based and scanned TOPIK PDFs and make individual questions searchable.
Architecture
- A FastAPI backend serves a lightweight HTML and JavaScript interface.
- Dictionary entries and TOPIK questions are stored in separate Chroma collections using multilingual-e5-small embeddings.
- Explicit grammar forms use exact or lexical lookup, while open-ended grammar and TOPIK topic queries use semantic retrieval.
- TOPIK preprocessing uses PyMuPDF for native PDF text and falls back to EasyOCR when necessary.
- TOPIK questions are stored together with their source and PDF coordinates so the original question can be rendered on demand.
Technical Stack
- Python
- FastAPI
- LangChain
- OpenAI API
- Chroma
- Multilingual Embeddings
- PyMuPDF
- EasyOCR
- HTML / JavaScript
Main Technical Challenges
- Keeping grammar explanations grounded in dictionary entries while using TOPIK only to provide real exam examples.
- Extracting individual questions and shared passages from TOPIK PDFs with different layouts and inconsistent text extraction.
- Generating a clean preview of the original exam question while preserving any shared passage or image needed to understand it.
Outcome
The finished application supports exact and semantic grammar search, TOPIK grammar and topic search, and on-demand previews of the original exam questions. The TOPIK parser was developed using seven exam papers and then tested on four additional exams that were not used during development. Low-confidence OCR cases are flagged for manual review.
Demo